
PrismML Shrinks 27B Model to 5.9GB
PrismML has released a compressed 27-billion-parameter reasoning model with a reported footprint of 5.9GB.
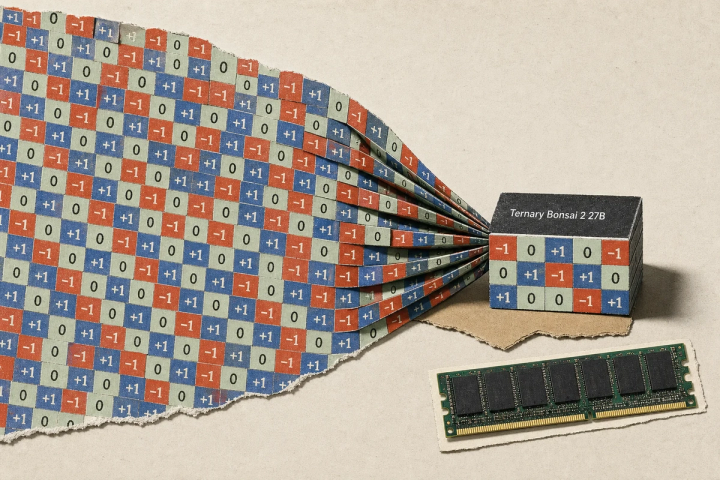
PrismML is pushing a different direction in the AI scaling race: making capable models dramatically smaller rather than assuming every workload belongs in a large data centre.
What happened
The company released Bonsai 2 27B, a compressed version of Qwen3.8 27B with a reported model footprint of 5.9GB.
The model uses ternary weights and supports reasoning, coding, vision and agentic tool use.
PrismML says the system is more than nine times smaller than the full-precision counterpart while retaining 98.2% of aggregate performance across its own benchmark suite. Those performance figures are company-reported and have not been independently validated here.
Why it matters
Smaller models can run on laptops, edge devices and private infrastructure where cloud inference may be too expensive, slow or sensitive.
If substantial capability can be preserved through aggressive compression, developers gain more options for local AI products and enterprises can keep more workloads inside controlled environments.
The bigger picture
AI infrastructure is developing along two competing paths: larger centralised clusters and more efficient local models. The second path could reduce inference costs and cloud dependence while opening new use cases for private and on-device AI. PrismML's release highlights how model efficiency is becoming a strategic layer of the AI stack.