Applied Compute introduces Ari Autoresearch
Running a model experiment is one task. Deciding what to try next is another.
Running a model experiment is one task. Deciding what to try next is another.
What happened
Applied Compute released Ari Autoresearch on 4 November, making it available to AC2 users to run and evaluate post-training experiments.
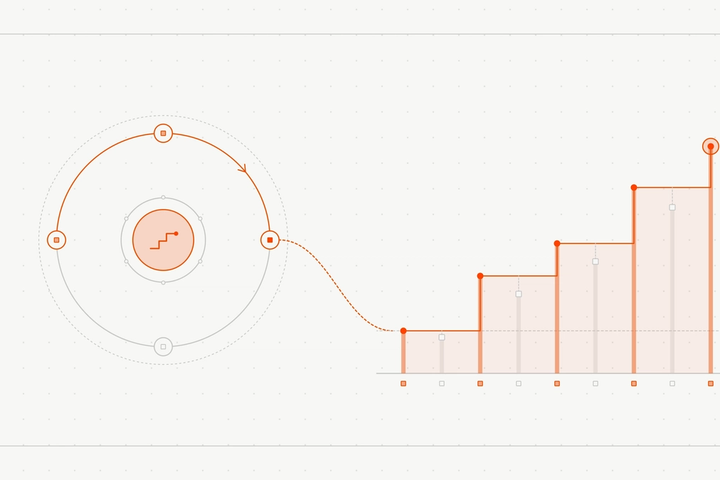
In a company-reported, 16-hour chess-puzzle experiment, Qwen3.5-9B's held-out reward rose from 0.118 to 0.629. Those figures are reward scores, not accuracy percentages.
Review needed: the result is a narrow, company-run experiment. Broader effectiveness is not verified enough.
Why it matters
Model development involves repeated decisions about training runs, evaluation and the next experiment. Automating parts of that loop could reduce manual work if the agent makes useful decisions and the gains hold up on relevant evaluations.
The bigger picture
The release is separate from Applied Compute's earlier funding announcement. It should be assessed as a bounded product and research result, rather than proof that AI can conduct general research autonomously or improve every model in the same way.